Chen Bo Calvin Zhang
Member of Technical Staff @ Google DeepMind | Previously @ OpenAI and Scale AI
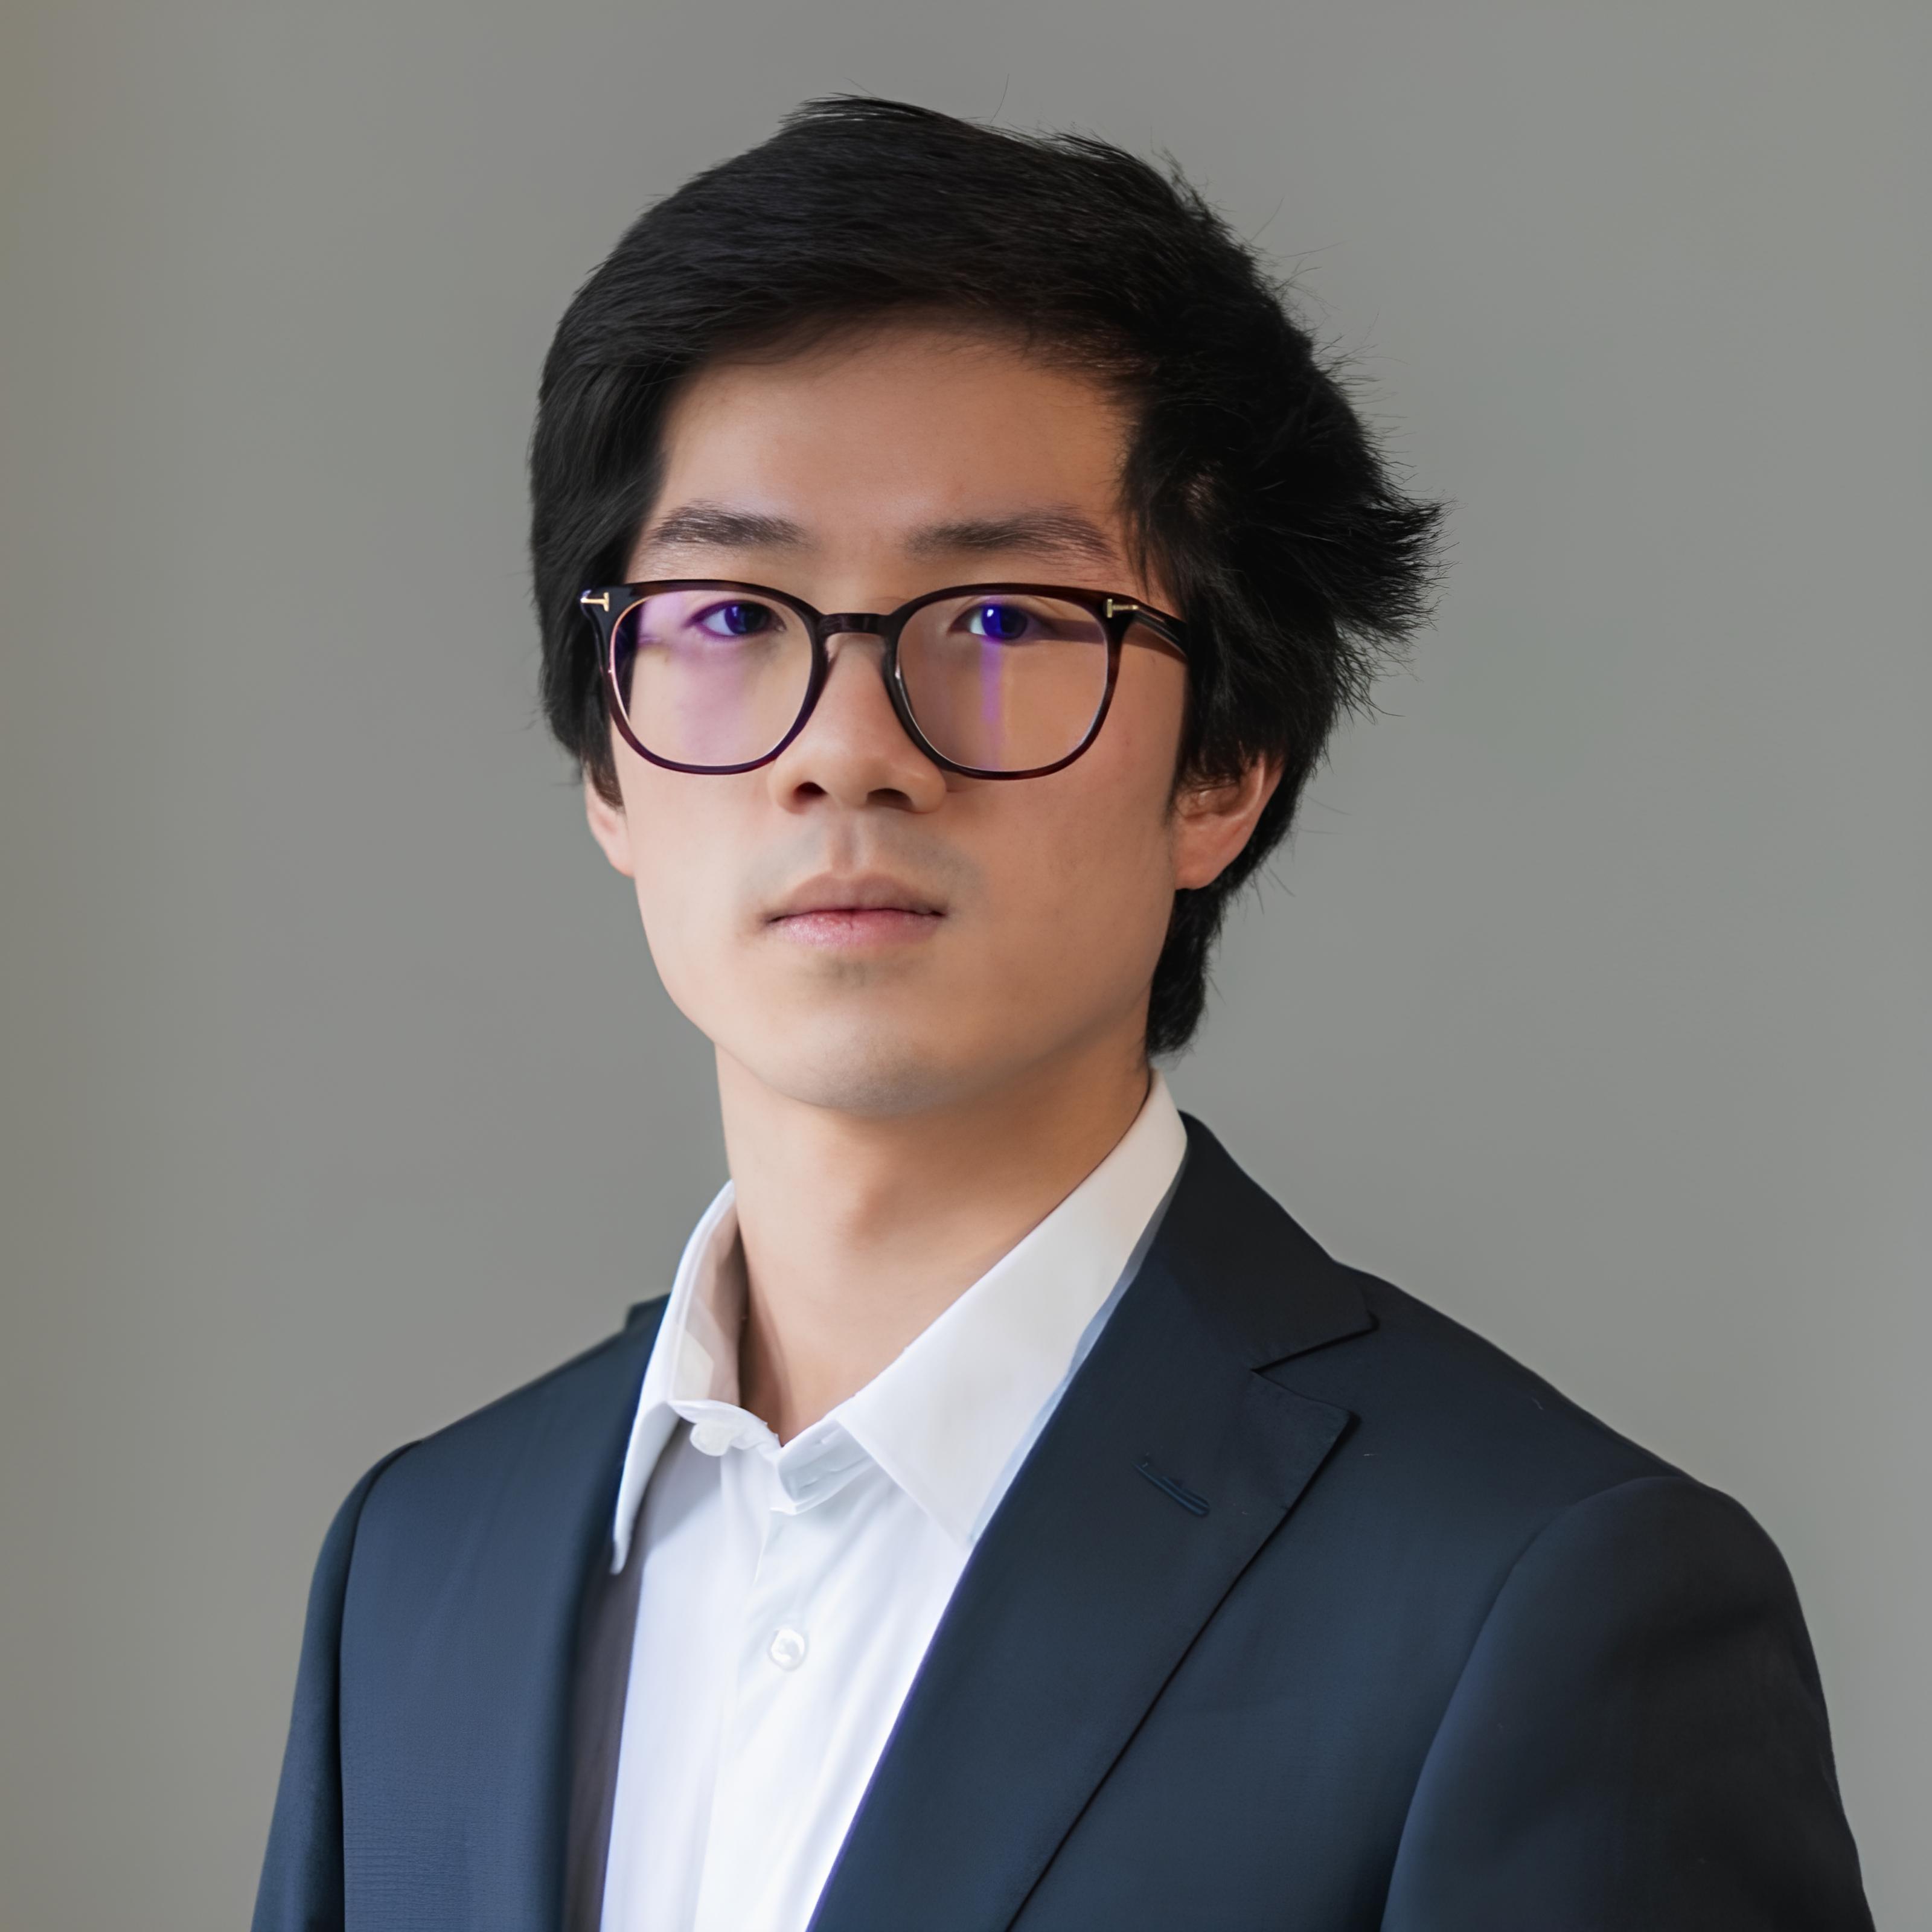
I’m a Member of Technical Staff at Google DeepMind, where I work on evals.
Previously, I worked on evals at OpenAI as a Research Program Manager and led ML research operations at Scale AI, where I designed evaluations, developed benchmarks, and managed leaderboards.
I also worked as a research intern at CHAI, where I collaborated with Micah Carroll on multi-turn red teaming strategies for large language models. Before that, I was a visiting scholar at MIT, where I focused on online learning and reward design for reinforcement learning with Zhang-Wei Hong, Aldo Pacchiano, and Pulkit Agrawal.
I received my MSc in Data Science from ETH Zurich, where I conducted research in preference-based reinforcement learning with Giorgia Ramponi. Earlier, I completed my BSc (Hons) in Computer Science and Mathematics from the University of Manchester, with a focus on adversarial attacks in deep reinforcement learning under the supervision of Tingting Mu.
My research interests include evaluation methodologies, sequential decision making, and AI safety and alignment.
Google Scholar / Twitter / GitHub / LinkedIn
News
| Oct 19, 2026 | I joined Google DeepMind as a Member of Technical Staff, working on evals |
|---|---|
| Jun 08, 2026 | I joined OpenAI as a Research Program Manager, working on evals |
| Apr 30, 2026 | SWE-Bench Pro, SciPredict, and SpreadsheetArena have been accepted to ICML 2026 |
| Feb 12, 2026 | I was on Chain of Thought to talk about ResearchRubrics, a benchmark to evaluate deep research agents |
| Feb 06, 2026 | Reliable Weak-to-Strong Monitoring of LLM Agents has been accepted to ICLR 2026 as an oral! |
| Jan 28, 2026 | Humanity’s Last Exam (HLE) has been published in Nature! |
| Jan 26, 2026 | Reliable Weak-to-Strong Monitoring of LLM Agents, ResearchRubrics, and MoReBench have been accepted to ICLR 2026 |
| Nov 20, 2025 | I recorded a podcast! Check out the latest episode of Chain of Thought on PRBench |
| Nov 13, 2025 | We published PRBench, a new benchmark to measure how well LLMs do on prefessional domains |
| Nov 12, 2025 | Check out our new paper ResearchRubrics: A Benchmark of Prompts and Rubrics For Evaluating Deep Research Agents |
| Aug 28, 2025 | We published Reliable Weak-to-Strong Monitoring of LLM Agents, extending our work on SHADE-Arena |
| Jun 19, 2025 | Excited to share our new paper SHADE-Arena, in collaboration with Anthropic |
| Jan 27, 2025 | I am excited to join Scale AI as a ML Research Ops Lead |
| Jan 22, 2025 | ORSO: Accelerating Reward Design via Online Reward Selection and Policy Optimization has been accepted at ICLR 2025 |
Latest Posts
| Nov 15, 2026 | Rediscovering Photography |
|---|---|
| Oct 14, 2026 | What Is an Em Dash—and When Should I Use One? |
| Aug 08, 2026 | I Am Assigning Myself Homework |
| Sep 16, 2024 | The Quantum Cheese Conundrum |
Selected Publications
2026
- ICLR
2025
2023
- ICML
 HIP-RL: Hallucinated Inputs for Preference-based Reinforcement Learning in Continuous DomainsIn ICML 2023 Workshop: The Many Facets of Preference-Based Learning, 2023